
- Status
- Verified
- Base model
- …
- Lineage
- …
- Unchanged from base
- …
- Trending
- #6
- Downloads, 30 days
- 15.8k
- Weights
- 66.3 GB
- Revision
In Nanbeige4.3, we take a foundational step toward pushing the boundaries of lightweight agents. Our strategy centers on building a high-capacity teacher agent first, which will subsequently anchor the distillation of advanced agentic capabilities into smaller models.
At a glance
- Task
- Text generation
- Input
- text
- Output
- text
- Parameters
- 33.1B
- Architecture
- Llama
- Context
- 512K tokens
- Precision
- BF16
- Format
- Safetensors
- Library
- transformers
- License
- Apache 2.0Commercial use
- Languages
- en, zh
- Base model
- Fine tuned from Nanbeige/Nanbeige4.3-33B-Base
- Released
- Oct 2026
- Updated
- Oct 2026
- Likes
- 689
- Downloads, all time
- 7,412
Architecture
- Layers
- 52
- Hidden size
- 7,168
- Attention
- 56 heads, grouped query, 8 KV heads
- Vocabulary
- 166,912
- Positions
- 524,288
- RoPE theta
- 120,000,000
- Tied embeddings
- No
Benchmarks
10 results, self reported by the authors.
| Benchmark | Score | Date | Evidence |
|---|---|---|---|
| harborframework/terminal-bench-2.1terminalbench_2_1 | 80.9 | Oct 2026 | Reported by source |
| harborframework/terminal-benchterminalbench_4 | 23.8 | Oct 2026 | Reported by source |
| datacurve/deep-swedeep_swe | 65.5 | Oct 2026 | Reported by source |
| ScaleAI/SWE-bench_ProSWE_Bench_Pro | 60.3 | Oct 2026 | Reported by source |
| benchflow/skillsbenchskillsbench_v1_1 | 61.1 | Oct 2026 | Reported by source |
| claw-eval/Claw-Evalgeneral | 78.3 | Oct 2026 | Reported by source |
| hkust-nlp/Toolathlontoolathlon_verified | 70.4 | Oct 2026 | Reported by source |
| collinear-ai/yc-benchmedium | 1025437 | Oct 2026 | Reported by source |
| Idavidrein/gpqadiamond | 89.5 | Oct 2026 | Reported by source |
| MathArena/aime_2026 | 95.2 | Oct 2026 | Reported by source |
Family
Models built on Nanbeige4.3-33B.
Run it
Loads with Transformers AutoModelForCausalLM and AutoTokenizer, pinned to the indexed revision.
from transformers import AutoModelForCausalLM, AutoTokenizer

model = AutoModelForCausalLM.from_pretrained("Nanbeige/Nanbeige4.3-33B", revision="df919e1e2cf077a22204c78b6c826bf3db18bc08")
processor = AutoTokenizer.from_pretrained("Nanbeige/Nanbeige4.3-33B", revision="df919e1e2cf077a22204c78b6c826bf3db18bc08")
Through the hub: the same tools, each file from a source that is up (Hugging Face, ModelScope, IPFS), at this revision. The second line checks every file against its address.
export HF_ENDPOINT=https://gethologram.ai
cd "$(hf download Nanbeige/Nanbeige4.3-33B --quiet)" && curl -s $HF_ENDPOINT/Nanbeige/Nanbeige4.3-33B/resolve/main/SHA256SUMS | sha256sum -c --quiet
Spaces
Used in 2 Spaces.
Read the full model card

1. Introduction
In Nanbeige4.3, we take a foundational step toward pushing the boundaries of lightweight agents. Our strategy centers on building a high-capacity teacher agent first, which will subsequently anchor the distillation of advanced agentic capabilities into smaller models.
To this end, we first introduce Nanbeige4.3-33B, designed as the flagship teacher model for the Nanbeige4.3 series. Delivering state-of-the-art agentic performance among open models in the ~30B parameter class, Nanbeige4.3-33B excels at complex coding and professional cowork tasks. It not only offers a powerful, cost-effective option for immediate real-world deployment, but also lays the necessary foundation to power our upcoming small model distillation pipeline (e.g., for Nanbeige4.3-3B).

2. Model Performance
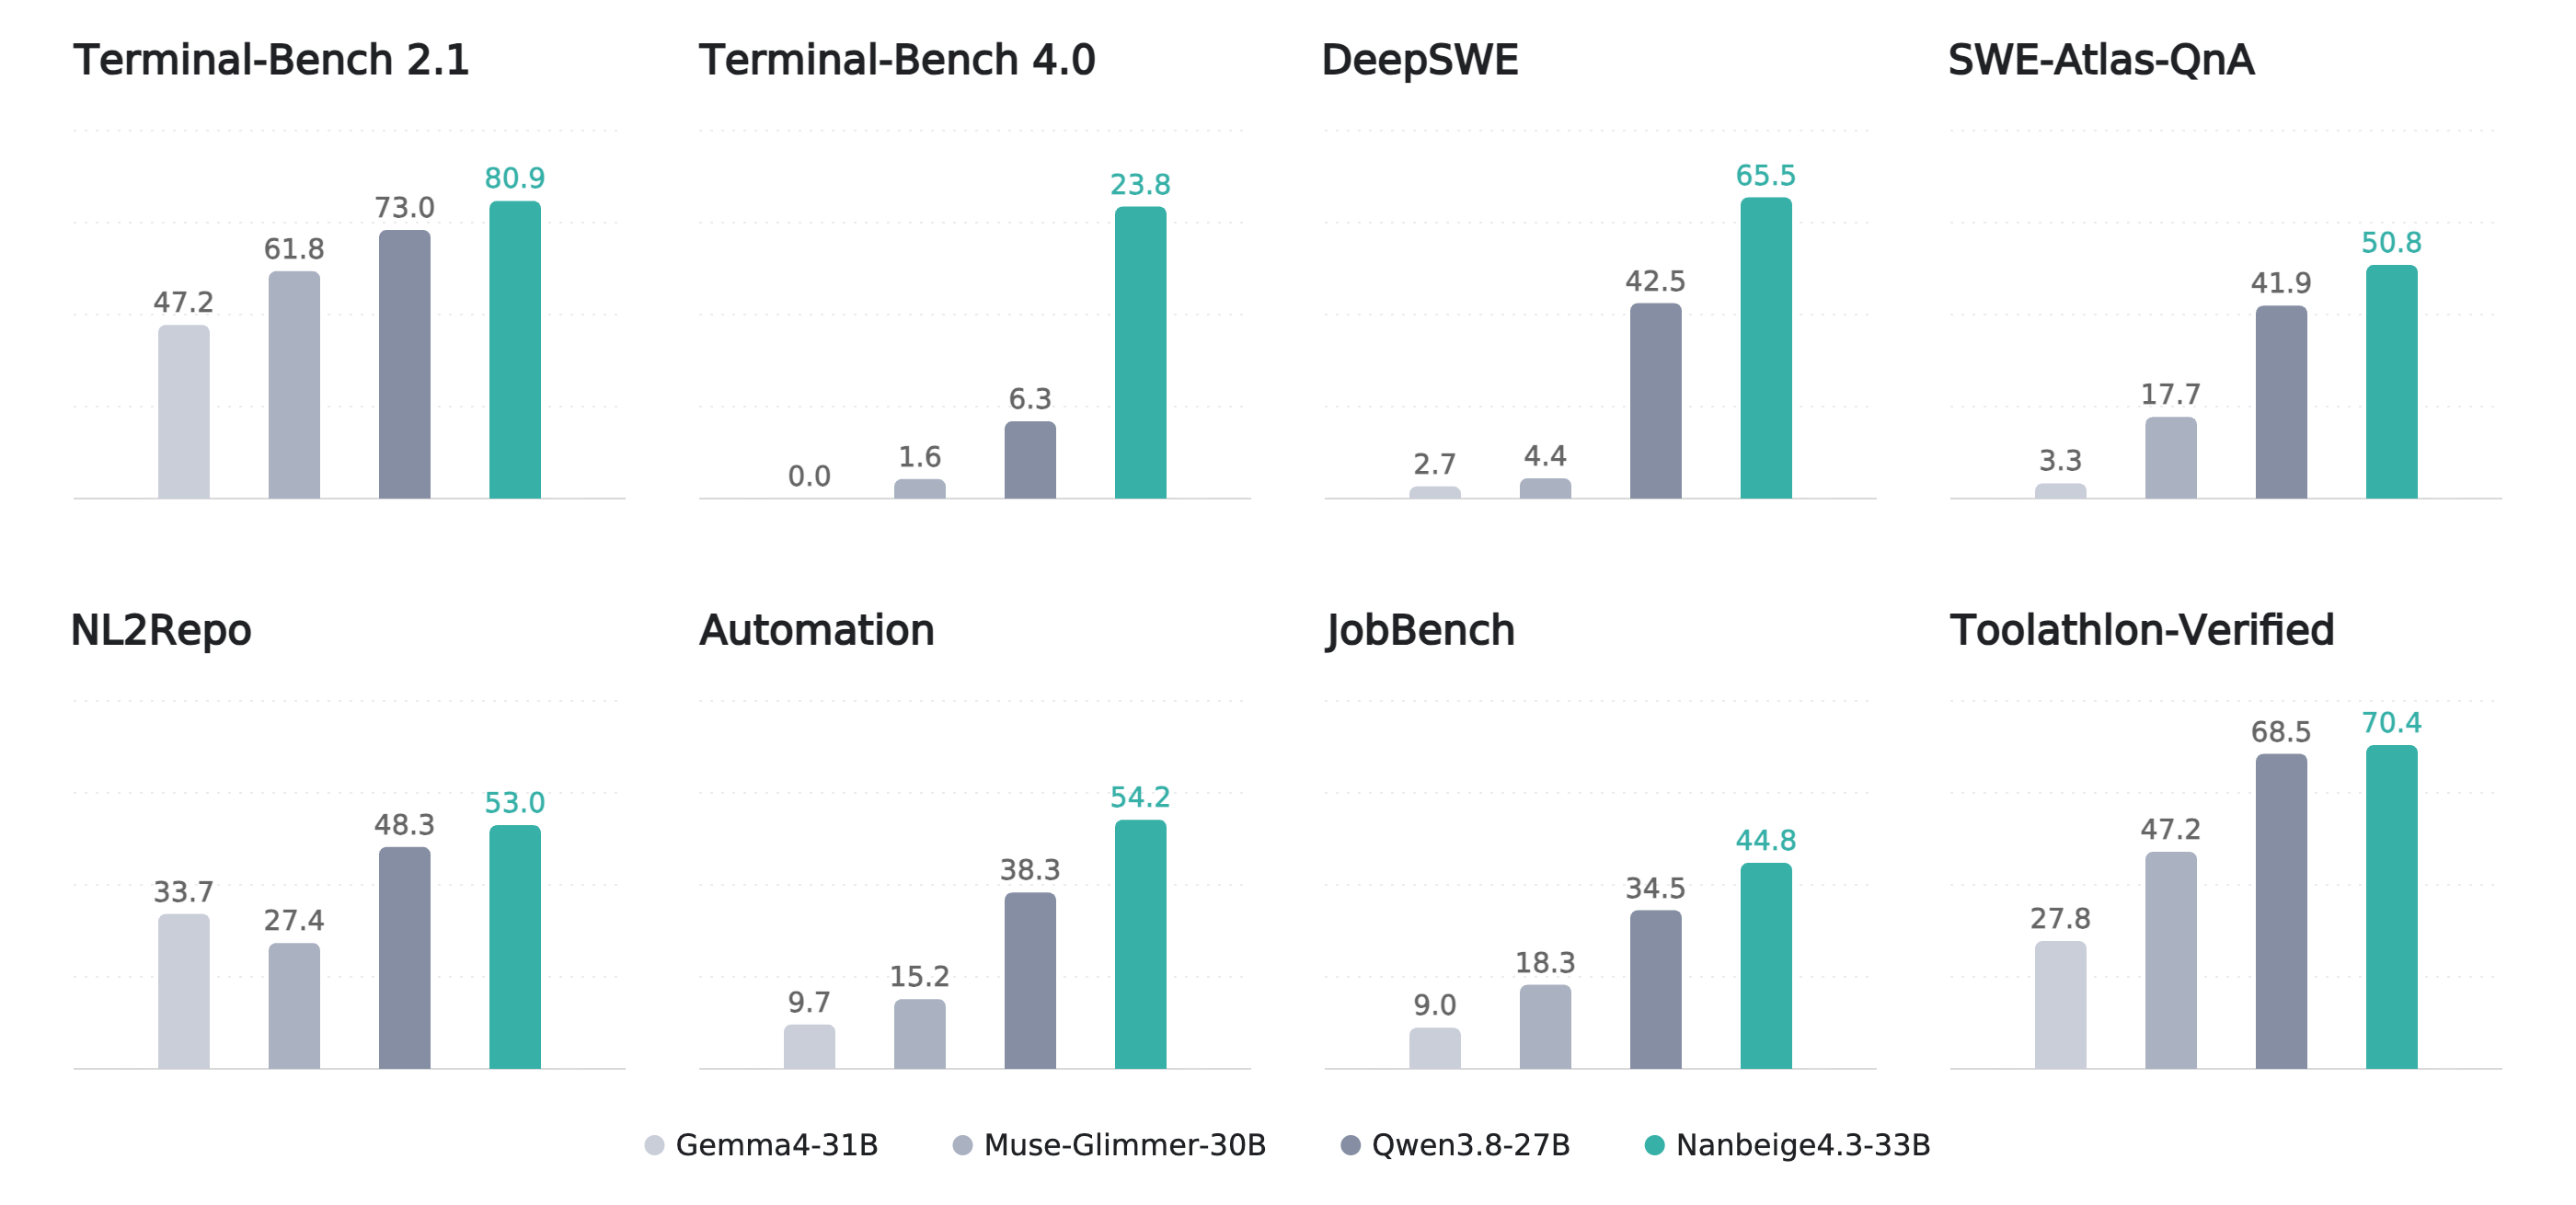
We compare Nanbeige4.3-33B with recently released frontier models at around the 30B-parameter scale: Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B. All models are evaluated at their highest thinking effort. For each benchmark, we use the same inference hyperparameters and harness across models.
CategoryBenchmarkNanbeige4.3-33B1Qwen3.8-27BMuse-Glimmer-30BGemma4-31B
Agentic CodingTerminal-Bench 2.1280.973.061.847.2
Terminal-Bench 4.0323.86.31.60.0
DeepSWE365.542.54.42.7
SWE-Bench Pro360.361.751.236.9
SWE-Atlas-QnA450.841.917.73.3
NL2Repo553.048.327.433.8
Scicode52.646.744.945.5
SkillsBench61.156.439.728.9
Agentic CoworkAutomation Bench654.238.315.29.7
JobBench744.834.516.69.0
GDPval884.886.475.871.4
Claw-Evalpass^3978.375.257.344.2
Toolathlon-Verified1070.468.547.227.8
DeepPlanning1263.349.221.419.4
EnterpriseOps-Gym1241.040.230.527.3
YC-bench11$1,025,437$641,290$513,978$265,152
Tau3-Bench1248.848.533.718.6
ReasoningGPQA Diamond89.589.283.591.3
AIME 202695.294.594.789.2
AA-LCR84.082.083.372.0
1 Nanbeige4.3-33B is evaluated with preserve_thinking=true in the chat template.
2 Terminal-Bench 2.1 is evaluated using Terminus 2.
3 Terminal-Bench 4 and DeepSWE are evaluated using mini-swe-agent v2.4.6.
4 SWE-Atlas-QnA is evaluated using mini-swe-agent v2.4.6. Answers are evaluated against 1,304 task-specific rubrics using GPT-6 Sol as the judge, with medium reasoning effort.
5 NL2Repo is evaluated using Claude Code.
6 Automation Bench v1.0.6 includes 600 publicly released tasks.
7 JobBench is evaluated with the Claude Code harness equipped with a search tool.
8 GDPval is scored using revised rubrics.
9 Claw-Eval is evaluated exclusively on the Claw-Eval General subset (comprising 157 single-turn user interaction tasks).
10 Toolathlon-Verified sets no max_tokens limit for individual model requests.
11 YC-bench retains only the most recent 10 turns of user dialogue as historical context before each model call.
12 DeepPlanning, EnterpriseOps-Gym, Tau3-Bench are evaluated using their official repositories.
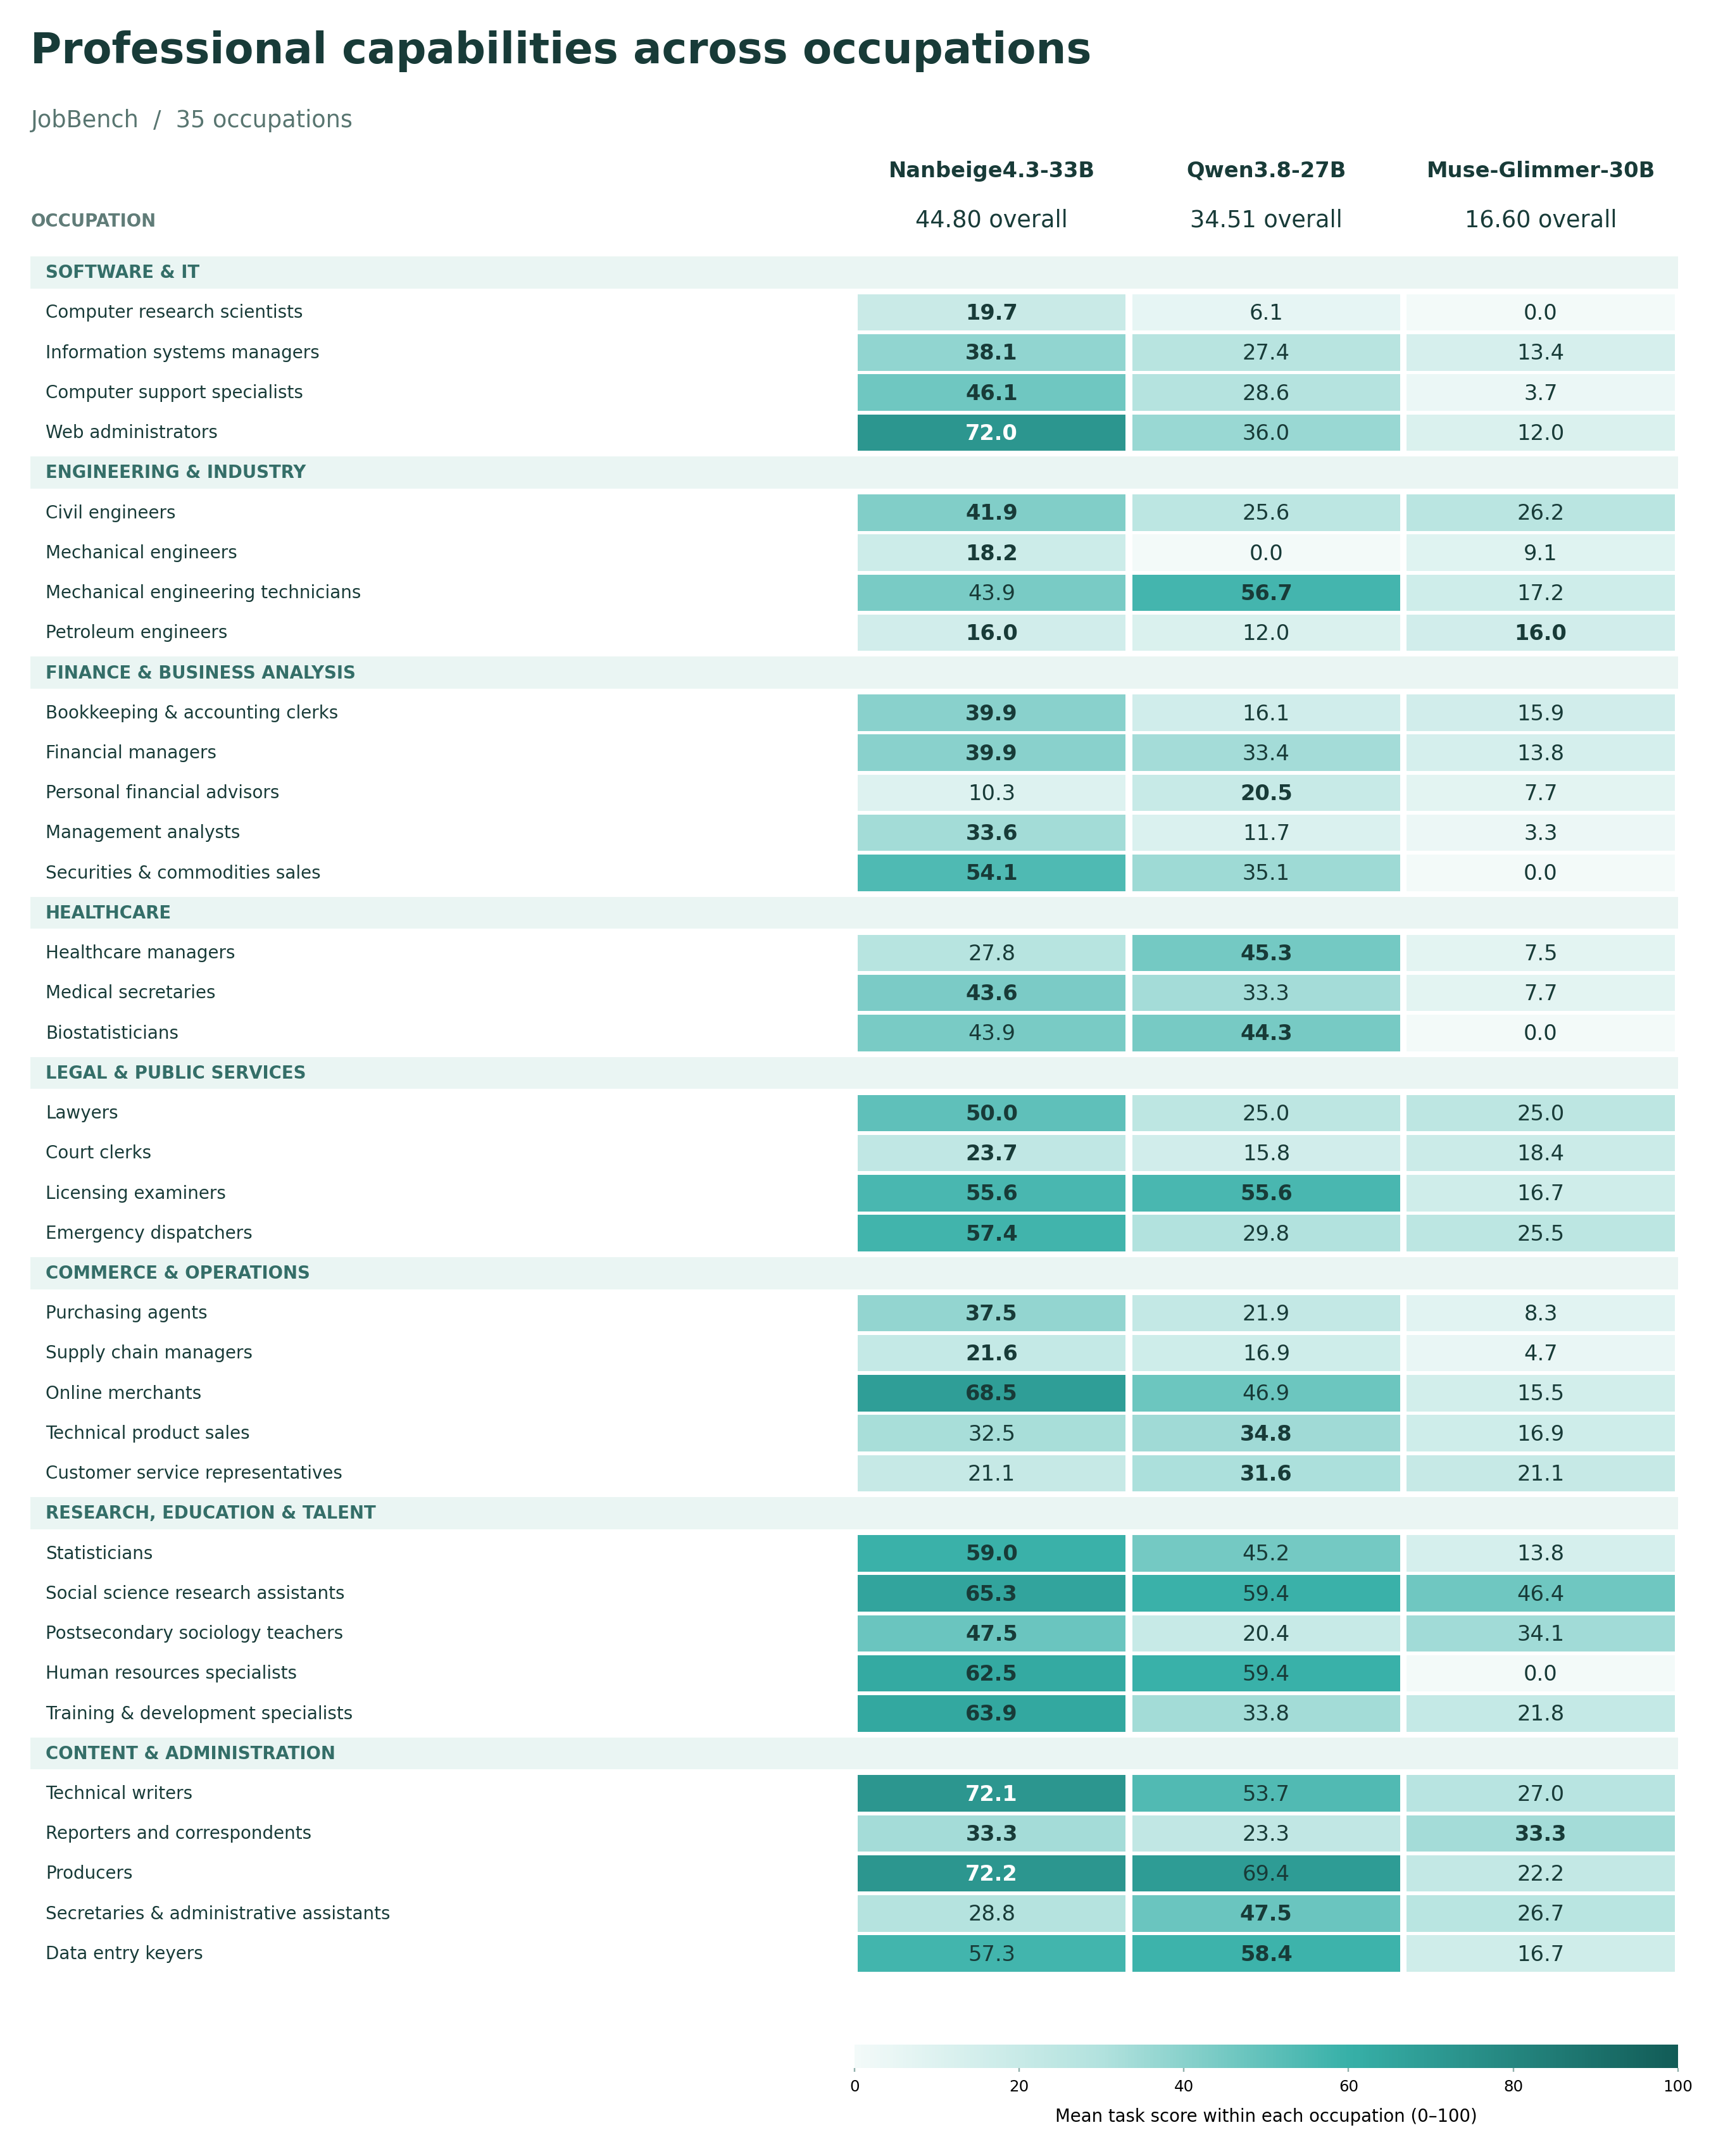
Nanbeige4.3-33B leads on most of the benchmarks, showing strong performance in both agentic coding and cowork tasks. Beyond its breadth across benchmarks, Nanbeige4.3-33B shows strong performance on agent tasks across a wide range of professions and industries. For example, on JobBench, it outperforms the baseline in most of the 35 occupations evaluated.

3. Quickstart
The tokenizer provides a configurable chat template for reasoning and tool-use scenarios:
enable_thinkingcontrols whether the model generates reasoning for the current response. It is enabled by default; set it toFalsefor non-thinking mode.preserve_thinkingcontrols whether reasoning from previous assistant turns is retained in a multi-turn conversation. We recommendFalsefor general chat and question answering, andTruefor multi-turn tool use, office tasks, and code-agent workflows.- Passing
toolsenables the tool-use template. We recommendtool_call_format="xml"for the best tool-calling performance;jsonis also supported for compatibility.
The model supports a context length of up to 524,288 tokens (512K).
We recommend adjusting the inference settings according to the target scenario:
| Scenario | Temperature | Top_p | Max New Tokens |
|---|---|---|---|
| Agentic and tool-use tasks | 1.0 | 0.95 | 65,536 |
| Reasoning and chat tasks | 0.6 | 0.95 | 262,144 |
You can run the model with Transformers, SGLang, or vLLM:
Transformers
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = 'Nanbeige/Nanbeige4.3-33B'
tokenizer = AutoTokenizer.from_pretrained(
  model_id,
  use_fast=False,
  trust_remote_code=True
)
model = AutoModelForCausalLM.from_pretrained(
  model_id,
  torch_dtype='auto',
  device_map='auto',
  trust_remote_code=True
)

messages = [{'role': 'user', 'content': 'Which number is bigger, 9.11 or 9.8?'}]
inputs = tokenizer.apply_chat_template(
  messages,
  add_generation_prompt=True,
  return_tensors='pt'
).to(model.device)
output_ids = model.generate(inputs, max_new_tokens=1024)
response = tokenizer.decode(output_ids[0][inputs.shape[-1]:], skip_special_tokens=True)
print(response)
SGLang
MODEL_PATH=/path/to/your/Nanbeige4.3-33B
python -m sglang.launch_server \
  --model-path ${MODEL_PATH} \
  --host 0.0.0.0 \
  --port 8000 \
  --tp-size 4 \
  --mem-fraction-static 0.8 \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen3_coder
vLLM
MODEL_PATH=/path/to/your/Nanbeige4.3-33B
vllm serve ${MODEL_PATH} \
  --host 0.0.0.0 \
  --port 8000 \
  --tensor-parallel-size 4 \
  --gpu-memory-utilization 0.8 \
  --enable-auto-tool-choice \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen3_coder
4. Contact
If you have any questions, please open an issue in this repository or contact us at nanbeige@kanzhun.com.
We also welcome collaborations to build domain-specific and industry-focused agents, including joint work on data and training.
5. Citation
If you find our model useful or would like to use it in your own work, please cite this Hugging Face project:
@misc{nanbeige43chat2026,
  title        = {Nanbeige4.3-33B},
  author       = {Nanbeige Team},
  year         = {2026},
  publisher    = {Hugging Face},
  howpublished = {\url{https://huggingface.co/Nanbeige/Nanbeige4.3-33B}}
}
Derived on Oct 28, 2026 from Hugging Face at revision df919e1e, README.md , config.json .
28 files, 66.3 GB. Every download is checked against its address.